Bioinformatics
From FASTQ to confident variant calls
The LockSeq pipeline checks each variant twice, in raw reads and in UMI consensus reads, then against your untreated control. You get one interactive report with a status for every site in your panel.
0.1% VAF
Standard limit of detection; each site’s limit is set by its own coverage
3 reads
Minimum UMI family size for a consensus read
20k / 3k
Standard sequencing depth per site on Illumina/MGI (raw / consensus)
3 platforms
Illumina, MGI and Oxford Nanopore, same pipeline
The pipeline
Six modules, from FASTQ to report
Every run goes through the same steps, from a 20-site panel to one designed for 1,000+ sites, so results compare across panels, sequencers and time.
01 · Read QC
Clean reads in, run quality on record
Trims adapters, filters low-quality reads and writes a quality summary for every sample in the run.
02 · UMI extraction
Each read keeps its molecule tag
Reads the unique molecular identifier off every read and stores it with the read before anything is aligned.
03 · Mapping
Reads placed on their target site
Aligns reads to the reference sequence of each target site, taken from your organism's reference genome (for example GRCh38 for human), then sorts and indexes the alignments.
04 · Consensus building
One consensus read per original molecule
Groups reads that share a UMI. A family of at least 3 reads becomes one consensus read, so errors that appear in a single read drop out.
05 · Variant annotation
Runs on raw and consensus reads
SNVs and indels, allele by allele
Aligns every read at the site against its reference and annotates substitutions, insertions and deletions per allele and per sample.
06 · Comparison & report
Treated vs control, both layers, one report
Checks each variant against both evidence layers and your untreated controls, assigns every site a data status and writes the interactive report.
Two layers of evidence
A variant is confirmed only when both layers agree
Raw reads show everything the sequencer saw. Consensus reads keep only what each original molecule carried.
A true variant is in every read from its molecule, so it survives consensus building. A random PCR or sequencing error is in only some of those reads, so the consensus drops it. The pipeline reports the variant frequency from the consensus layer and needs matching evidence in the raw reads before it calls a variant confirmed.
Variants below the raw threshold, or found only in raw reads, stay visible with a flag but aren't counted as confirmed. Consensus-only variants are removed as likely artifacts and listed in an audit file.
A site needs at least 1,000 raw and 30 consensus reads to be called. Sites below that are flagged in the report, not left out.
| Evidence flag | Consensus | Raw |
|---|---|---|
| ConfirmedVariant in both layers Reported variant | ✓ | ✓ |
| Raw support below limitRaw evidence matches but sits below the raw reporting threshold Flagged, not counted | ✓ | ~ |
| No raw supportConsensus variant not found in the raw reads Removed as artifact | ✓ | – |
| Not confirmedRaw-read variant with no consensus evidence Flagged, not counted | – | ✓ |
What consensus does to the data
In standard NGS reads, a true variant (violet) can hide in the background of random PCR and sequencing errors (grey). Consensus calling removes most of that background, so the variant stands out.
Checked against your control
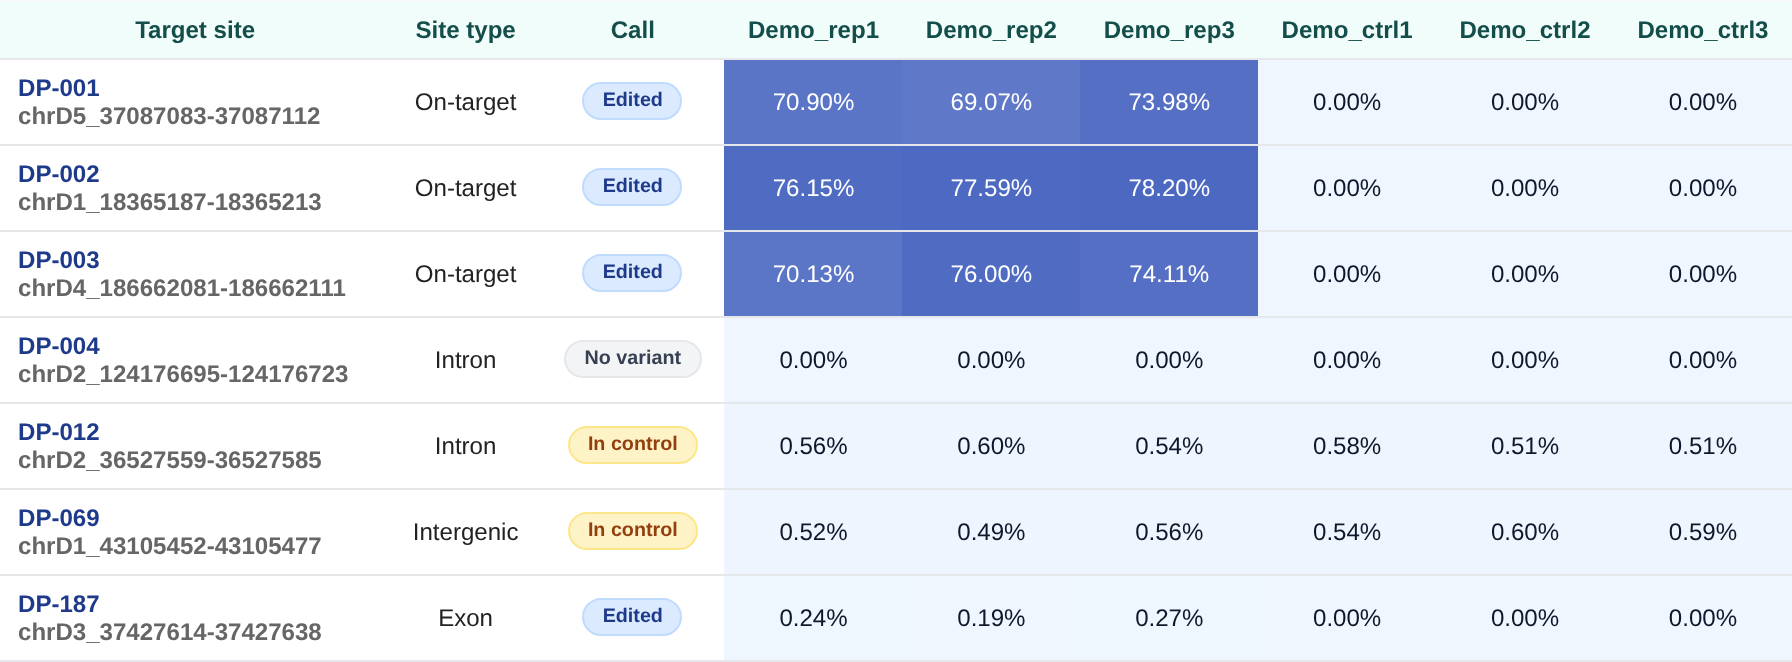
Variants in your control are kept apart from edits
Every genome differs from the reference at millions of positions.
So each treated sample is compared with your own untreated control as well as the reference genome. A variant at a similar frequency in treated and control samples is called in control. Only treated-associated variants count as editing signal.
Allele-level view
See the alleles behind every number
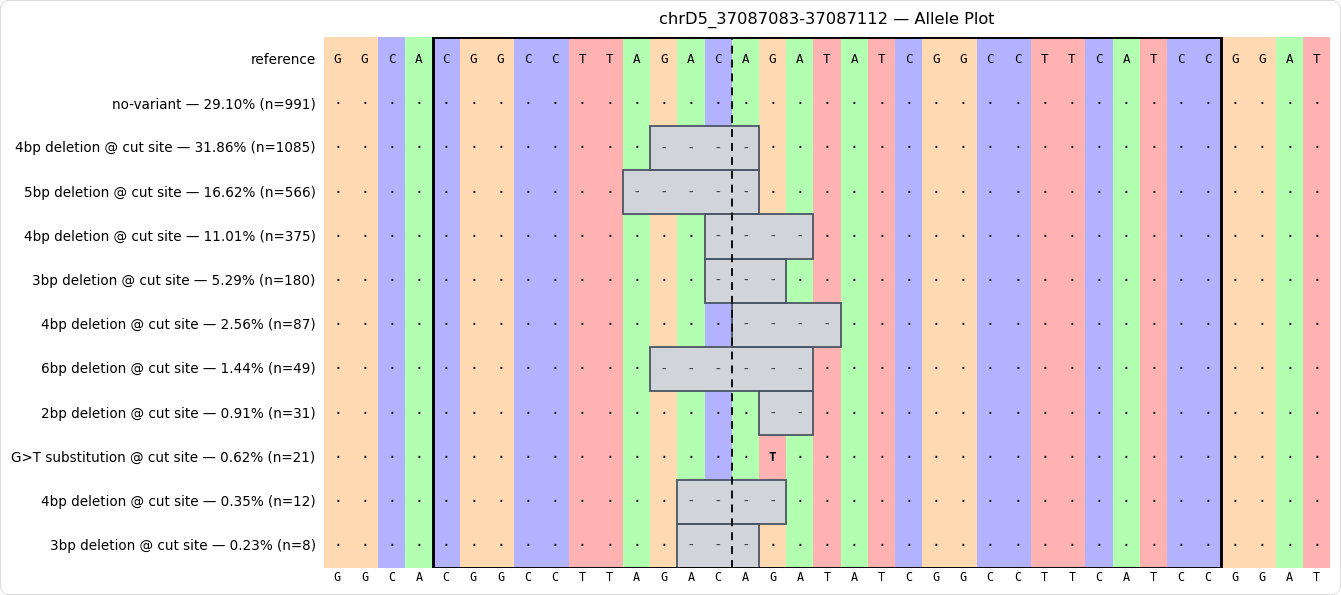
For each site and sample, the report shows the allele mix behind the frequency: which deletions, insertions and substitutions, how often, and from how many consensus reads. Any call can be checked by eye.
Both layers have their own allele plots, so you can put the raw and consensus view of the same site side by side.
Reporting rules
Every site in your panel gets a status
The thresholds are the same on every run and printed in every report, so you know exactly why a site was called the way it was.
Enough consensus support to report a variant frequency.
Raw reads show evidence, but consensus support is below the reporting guide.
Consensus depth below the interpretable threshold.
No usable consensus reads for one or more samples.
A capture or alignment pattern, such as reads from a second locus, flagged for manual review.
What you get back
The report and your raw data
Interactive HTML report
One self-contained file that opens in any browser. Filter by coverage, compare against controls, open the reads and export tables as CSV.
FASTQ and BAM files
Your raw and aligned data, ready for your own team to reanalyze in-house.
Analysis included
No separate software, analysis or per-run fees. The pipeline is part of the project price.
15 business days
From the day your DNA arrives in our lab in Solna, Stockholm to the delivered report.
See it for yourself
Open a full LockSeq report
Click through the sample report, or send us your nominated sites and we'll scope your panel within 24 hours.